Most AI marketing platforms have the same architecture: a thin application layer over a general-purpose foundation model accessed via a paid API. The application is where the product lives — the workflows, the UI, the integrations. The model is rented from someone else. It works. It is also the reason most of those platforms are priced per token, locked into a vendor's roadmap, and structurally unable to compound on your data.
Vannor is built differently. We run a purpose-built inference fabric organized as a mixture of experts. This post explains what that means and, more importantly, why it matters for the economics, quality, and trajectory of an AI marketing platform.
Why a single big model isn't the right shape
A single dense model is good at being a generalist. It will happily draft a blog post about plumbing fittings, then turn around and write Python, then translate a German legal contract. The cost of that flexibility is paid at every generation: every token of output activates the entire model. For a marketing platform, that's wasteful. You don't need the model that can write Python to be on the call when you're generating ad copy.
What mixture-of-experts changes
In a mixture-of-experts (MoE) fabric, the model is decomposed into many smaller expert networks. A learned router decides, for each token of input, which two or three experts to activate. The rest sit idle. So the fabric has the breadth of a much larger model, but the per-token cost of a much smaller one.
For marketing specifically, this is exactly the shape the problem wants. Marketing isn't one task — it's a collection of related but distinct tasks: gap analysis, brief generation, long-form drafting, ad-copy variants, image prompting, internal-link inference, schema generation, voice fingerprinting, audit summarization. Our autopilot kernel routes each one through the model's expert mixture and through the marketing-specific orchestration, brand-fingerprinting, and publishing layers we built around it.
Why we bet on efficiency, not size
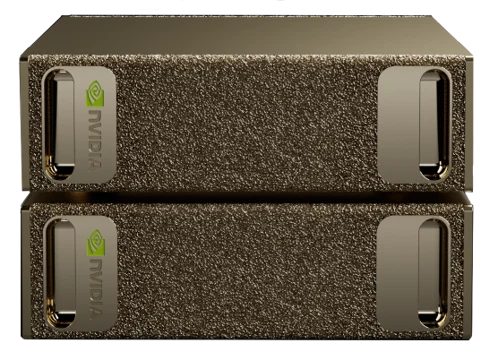
The industry reflex is "bigger model, better output." We took the opposite bet: a smaller, more efficient mixture-of-experts model that activates only a few billion parameters per token, running on dedicated NVIDIA Grace Blackwell silicon we own outright. Frontier-class output at a fraction of the compute — and because we own the hardware, there's no per-token API tax to pass on to you. Efficiency is the moat: it is what lets us price flat-rate instead of metering every word.
What it means for the customer
Three concrete consequences. Flat-rate pricing becomes possible. Because we're not paying a foundation provider per token, the marginal cost of generation is low enough that we can charge a flat platform fee instead of metering output. Brand voice gets sharper over time. The experts that handle long-form drafting can be fine-tuned on a per-tenant basis, so your brand's fingerprint isn't fighting against a generalist's defaults. The roadmap is ours, not someone else's. When a new marketing modality matters — say, podcast scripting, or three-second video ad copy — we add experts. We don't wait for a vendor to ship a new model.
Where this goes
A mixture-of-experts fabric is not just an architecture choice; it's a commitment to a different business model. You can't run an MoE fabric without owning the training, the routing, and the serving layer. Owning all three is expensive — but it's the only way an AI marketing platform compounds on a customer's data instead of paying tax to a vendor on every generation.
Now fix it
Start with the step-by-step guide, or check your own site first: the free audit scores one page's speed and on-page SEO.